Edge
The following are common scenarios that you may encounter when using Edge.
Scenario - Edge Hosts Ignore NTP Servers Configured in a Cloud-Init Stage
Edge hosts might ignore the Network Time Protocol (NTP) servers that you configure in a systemd-timesyncd drop-in
file. This occurs when a cloud-init stage in the Edge Installer user data or the OS pack writes the drop-in file and
creates the /etc/systemd/timesyncd.conf.d directory. The stage gives the directory permissions that only the root user
can access. systemd-timesyncd runs as the systemd-timesync user, so it cannot read the file and uses its default NTP
servers instead. If the default servers are unreachable, the clock of the Edge host does not synchronize.
The drop-in file still appears correct when you view it as the root user, so check the directory permissions and the
systemd-timesyncd logs instead.
Debug Steps
-
Establish an SSH connection to the affected Edge host.
-
Check the permissions of the drop-in directory.
stat --format='%a %n' /etc/systemd/timesyncd.conf.dThe issue affects the host if the permissions are
744.Example Output744 /etc/systemd/timesyncd.conf.d -
Check the
systemd-timesyncdlogs for permission errors.sudo journalctl --unit systemd-timesyncd --no-pager | grep 'Permission denied'Example Outputsystemd-timesyncd[1234]: Failed to open configuration file '/etc/systemd/timesyncd.conf.d/ntp.conf': Permission denied -
Give all users access to the directory, and then restart
systemd-timesyncd.sudo chmod 755 /etc/systemd/timesyncd.conf.d
sudo systemctl restart systemd-timesyncd -
Verify that
systemd-timesyncduses your NTP servers.timedatectl show-timesync --all | grep SystemNTPServersThe output lists the NTP servers from your drop-in file.
Example OutputSystemNTPServers=ntp.example.com -
To prevent the issue, add a
directoriesentry to the cloud-init stage that writes the drop-in file. Refer to Create a File in a New Directory for an example. If the stage is in the OS pack, deployed Edge hosts apply the updated OS pack during the next cluster upgrade and then reboot.
Scenario - Appliance Mode Edge Hosts Trust Compromised eMudhra Certificate Authorities
Appliance mode Edge hosts validate outbound TLS connections, such as connections to Palette and to image registries, against the trust store of the host operating system. This trust store can still trust the root certificates that the compromised eMudhra intermediate certificate authorities (CAs) chain to. For more information, refer to Security Advisory 024.
This workaround applies to Edge hosts that run Ubuntu, SUSE Linux Enterprise Micro (SLE Micro), Red Hat Enterprise Linux (RHEL), or Rocky Linux. Add a cloud-init stage to the OS pack of your cluster profile. The stage marks the affected root certificates as distrusted and rebuilds the trust store each time the Edge host boots.
Debug Steps
-
Log in to Palette.
-
From the left main menu, select Profiles.
-
Select the cluster profile that your Edge cluster uses, and create a new version of it.
-
In the new profile version, select the OS layer, and then add the cloud-init stage from the tab for the operating system of your Edge hosts to its YAML. If the YAML has no
stagessection, add the example as shown. Otherwise, merge the example into the existing YAML.-
If the YAML contains a
stagessection but noboot.beforestage, add theboot.beforestage to the existingstagessection. -
If the YAML already contains a
boot.beforestage, add only the list entry for your operating system (emudhra-distrust-debian,emudhra-distrust-suse, oremudhra-distrust-rhel) to the existingboot.beforelist.
- Ubuntu
- SLE Micro
- RHEL and Rocky Linux
stages:
  boot.before:
    - name: emudhra-distrust-debian
      commands:
        - |
          set -e
          conf=/etc/ca-certificates.conf
          if [ ! -f "$conf" ]; then
              echo "emudhra-distrust: $conf not found" >&2
              exit 1
          fi
          sed --in-place 's/\r$//' "$conf"
          for f in emSign_ECC_Root_CA_-_G3.crt emSign_Root_TLS_CA_-_G3.crt Comodo_AAA_Services_root.crt AAA_Certificate_Services.crt; do
              sed --in-place "s|^mozilla/$f\$|!&|" "$conf"
          done
          if [ -x /usr/sbin/update-ca-certificates ]; then
              /usr/sbin/update-ca-certificates --fresh
          else
              update-ca-certificates --fresh
fistages:
boot.before:
- name: emudhra-distrust-suse
commands:
- |
set -eu
if ! command -v trust >/dev/null 2>&1; then
echo "emudhra-distrust: trust not found" >&2
exit 1
fi
dirs="/etc/pki/trust/blacklist /etc/pki/trust/blocklist"
for dir in $dirs; do
mkdir --parents "$dir"
done
for pair in "emSign ECC Root CA - G3:emSign_ECC_Root_CA_-_G3" \
"emSign Root TLS CA - G3:emSign_Root_TLS_CA_-_G3" \
"Comodo AAA Services root:AAA_Certificate_Services"; do
label=${pair%%:*}
name=${pair##*:}
enc=$(printf '%s' "$label" | od --address-radix=n --format=x1 | tr --delete ' \n' | sed 's/../%&/g')
tmp=$(mktemp /tmp/emudhra.XXXXXX)
if trust extract --format=pem-bundle --filter="pkcs11:object=$enc;type=cert" \
--overwrite "$tmp" 2>/dev/null && [ -s "$tmp" ]; then
chmod 0644 "$tmp"
for dir in $dirs; do
cp "$tmp" "$dir/$name.pem"
done
rm --force "$tmp"
else
rm --force "$tmp"
echo "emudhra-distrust: label not found: $label" >&2
fi
done
if [ -x /usr/sbin/update-ca-certificates ]; then
/usr/sbin/update-ca-certificates
else
update-ca-certificates
fistages:
boot.before:
- name: emudhra-distrust-rhel
commands:
- |
set -e
if ! command -v trust >/dev/null 2>&1; then
echo "emudhra-distrust: trust not found" >&2
exit 1
fi
dirs="/etc/pki/ca-trust/source/blacklist /etc/pki/ca-trust/source/blocklist"
for dir in $dirs; do
mkdir --parents "$dir"
done
for pair in "emSign ECC Root CA - G3:emSign_ECC_Root_CA_-_G3" \
"emSign Root TLS CA - G3:emSign_Root_TLS_CA_-_G3" \
"Comodo AAA Services root:AAA_Certificate_Services"; do
label=${pair%%:*}
name=${pair##*:}
enc=$(printf '%s' "$label" | od --address-radix=n --format=x1 | tr --delete ' \n' | sed 's/../%&/g')
tmp=$(mktemp /tmp/emudhra.XXXXXX)
if trust extract --format=pem-bundle --filter="pkcs11:object=$enc;type=cert" \
--overwrite "$tmp" 2>/dev/null && [ -s "$tmp" ]; then
chmod 0644 "$tmp"
for dir in $dirs; do
cp "$tmp" "$dir/$name.pem"
done
rm --force "$tmp"
else
rm --force "$tmp"
echo "emudhra-distrust: label not found: $label" >&2
fi
done
if [ -x /usr/bin/update-ca-trust ]; then
/usr/bin/update-ca-trust
else
update-ca-trust
fi -
-
Save your changes.
-
Update your cluster to use the new profile version.
warningApplying the updated OS pack reboots the Edge hosts in the cluster. Plan the update for a maintenance window.
-
After the Edge hosts reboot, connect to an Edge host using SSH, and issue the command for its operating system to check whether the trust store still contains the affected root certificates.
- Ubuntu
- SLE Micro
- RHEL and Rocky Linux
ls /etc/ssl/certs/ | grep --extended-regexp 'emSign_ECC_Root_CA_-_G3|emSign_Root_TLS_CA_-_G3|Comodo_AAA_Services_root|AAA_Certificate_Services'trust list --filter=ca-anchors | grep --extended-regexp 'emSign ECC Root CA - G3|emSign Root TLS CA - G3|Comodo AAA Services root'trust list --filter=ca-anchors | grep --extended-regexp 'emSign ECC Root CA - G3|emSign Root TLS CA - G3|Comodo AAA Services root'If the command returns no output, the Edge host no longer trusts these root certificates.
Scenario - Provider Image Download Times Out on Slow Network Connections
Edge hosts with limited network bandwidth may fail to download and extract the provider image during cluster provisioning or agent upgrades.
Starting with Palette agent version 4.10.3, each provider image download and extraction attempt has a fixed time limit. The limit is 45 minutes in Palette agent versions 4.10.3 through 4.10.9, and 6 hours in version 4.10.10 and later. If an attempt does not complete within that time, the Palette agent starts the next attempt from the beginning, because it does not resume partially completed downloads.
If the attempts repeatedly reach the time limit, the cluster may remain in the Provisioning state, or the agent upgrade may not complete.
Debug Steps
-
Check the Palette agent logs on the affected Edge host to identify provider image download failures.
journalctl --unit stylus-agent --no-pager | grep --extended-regexp 'downloading image|not found locally|found image|extracted|context deadline exceeded|failed to apply'Review the logs for the following messages:
downloading imageandimage <image-reference> not found locallyindicate that the Palette agent is downloading the provider image over the network.context deadline exceededindicates that an attempt reached the time limit.failed to apply archiveandfailed to apply os upgrademay appear when the download or extraction does not complete.
If these messages repeat at intervals that match the time limit for your Palette agent version, the download is consistently exceeding the time limit.
-
Make the provider image available locally to avoid downloading it over a bandwidth-constrained connection.
Use
palette content buildto package the required provider image into a content bundle on a machine with a fast connection to the image registry. Transfer the content bundle to the affected Edge host and extract it into the local bundle store. For new Edge hosts, you can instead include the content bundle in the Edge Installer ISO.The Palette agent then uses the local provider image instead of downloading it, so the time limit no longer applies.
-
Verify that the provider image is available locally.
Run the command from step 1 again and review the Palette agent logs. The logs should show the following message.
Example Outputfound image <image-reference> in local bundleThis confirms that the Palette agent found the image locally instead of starting another network download. Verify that the agent upgrade completes and that the cluster returns to the Healthy state in Palette.
If you cannot make the provider image available locally, increase the network bandwidth available to the Edge host so that the download and extraction complete within the time limit.
Scenario - Agent Mode Edge Hosts Do Not Claim the Control Plane VIP after a Reset
On Palette versions earlier than 4.10.25, a reset removes kube-vip.tar, the kube-vip image archive, from
agent mode Edge hosts. A reset occurs, for example, when you delete a
cluster, remove a host from its node pool, or reset the host. When you add a reset host to a new cluster, the Palette
agent cannot import the kube-vip image, so kube-vip does not start. As a result, the control plane virtual IP (VIP)
address of the cluster is not claimed, the remaining hosts cannot join the cluster, and cluster provisioning does not
complete. Palette does not report an error, but the Palette agent logs the warning
failed to link kube-vip image tar after retries.
This issue does not affect hosts that you have not reset or hosts that you reset on Palette version 4.10.25 or later.
Debug Steps
-
Establish an SSH connection to the Edge host.
-
Check whether the kube-vip image archive is present.
sudo ls --format=long --dereference /usr/local/spectrocloud/content/images/kube-vip.tarIf the output lists the file, this host is not affected, and you can continue with the next Edge host in the cluster. If the output contains
No such file or directory, continue to the next step. -
Find the version directory of the active Palette agent.
sudo readlink /opt/spectrocloud/bin/stylus-agentThe version directory is the path segment that follows
/opt/spectrocloud/updates/, such as4.10.4in the following example output.Example Output/opt/spectrocloud/updates/4.10.4/opt/spectrocloud/bin/stylus-agentIf the command does not return any output, the Palette agent on this host has not been upgraded since you installed it, and the reset removed the only copy of the archive. In this case, contact Spectro Cloud support at support@spectrocloud.com. To avoid this on other hosts whose Palette agent has not been upgraded, back up the archive before you reset them. Refer to Back Up the kube-vip Image Archive before a Reset.
-
Copy the kube-vip image archive from the version directory.
sudo cp --remove-destination /opt/spectrocloud/updates/<version>/usr/local/spectrocloud/content/images/kube-vip.tar /usr/local/spectrocloud/content/images/kube-vip.tarReplace
<version>with the version directory from step 3. -
Restart the Palette agent service.
sudo systemctl restart spectro-stylus-agent.service -
Confirm that the kube-vip image archive is present. The output lists the file.
sudo ls --format=long --dereference /usr/local/spectrocloud/content/images/kube-vip.tar -
Repeat steps 1 - 6 on each Edge host in the cluster.
The copied archive persists after a Palette agent upgrade, but not after another reset. If you reset the host again on a Palette version earlier than 4.10.25, repeat these steps.
Back Up the kube-vip Image Archive before a Reset
On Palette versions earlier than 4.10.25, a reset removes the only copy of the kube-vip image archive from an agent mode Edge host whose Palette agent has not been upgraded since you installed it. Back up the archive before you reset the host, and restore it before you add the host to a new cluster.
-
Establish an SSH connection to the Edge host.
-
Check whether the Palette agent on the host has been upgraded since you installed it.
sudo readlink /opt/spectrocloud/bin/stylus-agentIf the command returns a path, the agent has been upgraded, and its version directory keeps a copy of the archive. You do not need a backup, but after the reset, restore the archive from the version directory. Refer to Agent Mode Edge Hosts Do Not Claim the Control Plane VIP after a Reset. If the command does not return any output, continue to the next step.
-
Back up the archive to a location that the reset does not remove.
sudo cp /usr/local/spectrocloud/content/images/kube-vip.tar /opt/spectrocloud/kube-vip.tar.backup -
Delete the cluster, remove the host from its node pool, or reset the host. After the reset completes, establish an SSH connection to the Edge host again.
-
Before you add the host to a new cluster, restore the archive.
sudo cp --remove-destination /opt/spectrocloud/kube-vip.tar.backup /usr/local/spectrocloud/content/images/kube-vip.tar -
Restart the Palette agent service.
sudo systemctl restart spectro-stylus-agent.service -
Confirm that the kube-vip image archive is present. The output lists the file.
sudo ls --format=long --dereference /usr/local/spectrocloud/content/images/kube-vip.tar
Keep the backup file. The reset does not remove it, so you can repeat steps 4 - 7 each time you reset the host.
Scenario - Custom systemd Drop-In Files Do Not Apply After Migration to systemd Extensions
After you move a PXK-E Edge cluster to systemd extensions on a Palette version earlier than 4.10.25, custom drop-in files for the containerd and Kubelet services stop applying, and no error is reported. For example, image pulls from a private registry that uses a Kubelet credential provider fail, or a containerd HTTP proxy stops applying.
This occurs because the migration moves the entire /etc/systemd/system/containerd.service.d/ and
/etc/systemd/system/kubelet.service.d/ directories to a backup directory, instead of moving only the drop-in files
that Palette ships. Clusters that you move on version 4.10.25 or later are not affected.
Debug Steps
-
Establish an SSH connection to the Edge host.
-
List the drop-in files that the migration moved to the backup directory.
sudo ls --recursive /opt/.extensions/migrations/backups/kubeadm-sysext-migrations -
List the drop-in files that Palette ships. A file in the backup directory with the same name as one of these files is a Palette drop-in file, so do not copy it back. Every other file in the backup directory is one of your custom drop-in files.
ls /usr/lib/systemd/system/containerd.service.d/ /usr/lib/systemd/system/kubelet.service.d/ -
Re-create the original directory, and then copy each custom drop-in file back to it.
sudo mkdir --parents /etc/systemd/system/<service-name>.service.d/
sudo cp <backup-file-path> /etc/systemd/system/<service-name>.service.d/
Replace
<backup-file-path>with the path to the custom drop-in file in the backup directory. Replace<service-name>withcontainerdorkubelet, depending on the directory that the file came from. -
Reload systemd, and then restart the containerd and Kubelet services.
sudo systemctl daemon-reload
sudo systemctl restart containerd kubelet -
Confirm that systemd applies your custom drop-in files. The output lists each file that applies to a service in a comment line that starts with
#, followed by the path to the file.systemctl cat containerd kubelet -
Repeat steps 1 - 6 on each Edge host in the cluster.
Scenario - Missing multipath-tools Package on Edge Images
Edge hosts that rely on multipath storage configurations may experience storage accessibility issues because the
multipath-tools package is missing from Edge installer and provider images built with
CanvOS 4.8.8 and later on the Kairos
v3.5.9 base image. A system cleanup step in Kairos v3.5.9 removes the package. CanvOS 4.10.3 and later, which correspond
to Palette 4.10.13 and later, use a Kairos version that includes multipath-tools on Ubuntu 22.04 and later.
To resolve this issue on earlier CanvOS versions, add multipath-tools to your images.
Debug Steps
-
Add
multipath-toolsto your CanvOSDockerfilebefore building the installer ISO or provider images. For example, add the following line for Ubuntu-based builds.RUN apt-get update && apt-get install --yes multipath-toolsFor FIPS builds, add the package to the base image Dockerfile for the respective operating system.
The
multipath-toolspackage is known to cause issues on Ubuntu 20.04. If unexpected behavior occurs, removemultipath-tools. -
Build the installer ISO and provider images. Refer to Build Edge Artifacts for more information on customizing your
Dockerfile.
Scenario - Cluster Nodes Fail to Become Ready on Kubernetes v1.35.x
On Edge clusters configured with Kubernetes v1.35.x, hosts running OSes that default to cgroup v1, such as Ubuntu 20.04 and earlier and RHEL 7–8, may cause Kubelet to fail to start, with nodes entering a restart loop.
To resolve this issue, configure the host operating system to use cgroup v2.
Debug Steps
Enable cgroup v2 in User Data When Deploying a New Cluster
When provisioning a new cluster, add the following parameter in the user-data file.
#cloud-config
install:
  grub_options:
    extra_cmdline: "systemd.unified_cgroup_hierarchy=1"
This ensures nodes boot with cgroup v2 enabled.
Enable cgroup v2 in Provider Image When Upgrading to Kubernetes v1.35.x
Build a new provider image with cgroup v2 enabled by uncommenting the following line in the Dockerfile.
RUN sed -i 's|\(set baseCmd="[^"]*\)"|\1 systemd.unified_cgroup_hierarchy=1"|' \
    /etc/cos/bootargs.cfg
This makes cgroup v2 the default for all nodes created from the image.
Verification
After applying either method, verify that cgroup v2 is enabled by issuing the following command on any cluster node.
stat --file-system --format=%T /sys/fs/cgroup
cgroup2fs
Scenario - Intermittent ImagePullBackOff Errors on Airgap Edge Clusters with Kubernetes v1.35.x
On airgap Edge clusters at Kubernetes v1.35.x or later, pods may intermittently fail to start with an
ImagePullBackOff status, even though the image is already present on the node. All three Edge Kubernetes distributions
are affected: Palette Optimized K3s,
Palette Optimized RKE2, and
Palette eXtended Kubernetes Edge (PXK-E). The issue
most commonly affects the palette-webhook and palette-lite-controller-manager pods, and it
also affects pods that use the spectro-drive, crony, and spectro-import-presetup images. The pod events show a
timeout while reaching an external registry, similar to the following.
Failed to pull image "<registry>/<image-name>:<tag>":
Head "https://<registry>/v2/<image-name>/manifests/<tag>": dial tcp 192.0.2.10:443: i/o timeout
Kubernetes v1.35 enables the Ensure Secret Pulled Images
feature, which tracks whether each image was pulled using verified registry credentials. Kubelet, the Kubernetes node
agent that manages the pods on each node, keeps these pull records on disk. Its default policy for this feature,
NeverVerifyPreloadedImages, trusts images that were preloaded onto the node unless a pull record already exists for
them.
In an airgap deployment, images are loaded onto the node from the Palette content bundle instead of being pulled from a registry. Depending on the timing of the bundle import relative to when the first pod is scheduled, Kubelet can write a pull record for a bundle image that contains no credential mapping. From that point on, Kubelet stops treating the image as preloaded and forces a new pull from the image's original public registry, which cannot succeed in an airgap environment and times out. The failure is sticky, so it persists for every later pod that uses the image until you remove the record and restart Kubelet on the node, which clears its in-memory record cache. On K3s and RKE2, Kubelet runs inside the distribution's own process rather than as a separate service, so you restart that process instead of a Kubelet service.
Because the behavior depends on import timing, the issue is intermittent, and some nodes or images are affected while others in the same cluster are not.
The issue affects new cluster deployments and clusters that reach Kubernetes v1.35.x or later without the required Kubelet setting in place. An upgrade from Kubernetes v1.34.5 to v1.35.2 has been verified to complete without the issue when the target pack already carries that setting.
On K3s and RKE2, pack version 1.35.6 includes an Airgap preset that applies the setting for you, and pack versions
1.35.2 and 1.35.3 need a manual values override instead. The preset is not enabled by default, so a cluster on pack
version 1.35.6 remains exposed to the issue until you enable it. To apply the setting, refer to
Prevent the Issue on a New Cluster.
On PXK-E, no released pack version includes the preset, so apply the setting as a manual values override on every
affected pack version. PXK-E also requires a second file that K3s and RKE2 do not. PXK-E runs Kubelet as a standalone
service that does not read the drop-in directory unless you point it there, so you must set the Kubelet --config-dir
argument as well. Omitting it leaves the drop-in on disk but unread, which looks identical to the setting never having
been applied.
If an affected pod also serves a webhook that manages a Custom Resource Definition (CRD) conversion, the control plane may return errors while reading cluster resources until that pod recovers. An upgrade can partially apply CRD changes before the new webhook pod starts, which leaves the control plane unable to read cluster resources through the webhook until you recover the pod.
Debug Steps
Prevent the Issue on a New Cluster
The required setting is a Kubelet configuration drop-in file that must exist before any images are imported onto the node. How you apply it depends on your Kubernetes pack and version.
-
K3s or RKE2 pack version
1.35.6or later - In the Presets panel of the Kubernetes layer, set Airgap to Enable. The preset name isairgap. This preset is not enabled by default, so you must select it explicitly. -
K3s or RKE2 pack versions
1.35.2and1.35.3, or any PXK-E pack version - These versions do not include the preset. In thevalues.yamlfile of the Kubernetes layer, add the configuration manually to the existinginitramfsstage, alongside any otherdirectoriesorfilesentries.
Select your Kubernetes distribution for the configuration to apply. For more information about cloud-init stages, refer to Cloud-Init Stages.
- K3s
- RKE2
- PXK-E
stages:
  initramfs:
    - directories:
        - path: "/var/lib/rancher/k3s/agent/etc/kubelet.conf.d"
          permissions: 0700
      files:
        - path: /var/lib/rancher/k3s/agent/etc/kubelet.conf.d/10-image-pull-creds.conf
          permissions: 0600
          content: |
            apiVersion: kubelet.config.k8s.io/v1beta1
            kind: KubeletConfiguration
            featureGates:
              KubeletEnsureSecretPulledImages: true
            imagePullCredentialsVerificationPolicy: NeverVerify
stages:
  initramfs:
    - directories:
        - path: "/var/lib/rancher/rke2/agent/etc/kubelet.conf.d"
          permissions: 0700
      files:
        - path: /var/lib/rancher/rke2/agent/etc/kubelet.conf.d/10-image-pull-creds.conf
          permissions: 0600
          content: |
            apiVersion: kubelet.config.k8s.io/v1beta1
            kind: KubeletConfiguration
            featureGates:
              KubeletEnsureSecretPulledImages: true
            imagePullCredentialsVerificationPolicy: NeverVerify
stages:
  initramfs:
    - directories:
        - path: "/etc/kubernetes/kubelet.conf.d"
          permissions: 0700
      files:
        - path: /etc/kubernetes/kubelet.conf.d/10-image-pull-creds.conf
          permissions: 0600
          content: |
            apiVersion: kubelet.config.k8s.io/v1beta1
            kind: KubeletConfiguration
            featureGates:
              KubeletEnsureSecretPulledImages: true
            imagePullCredentialsVerificationPolicy: NeverVerify
        - path: /etc/default/kubelet
          permissions: 0644
          content: |
            KUBELET_EXTRA_ARGS="--config-dir=/etc/kubernetes/kubelet.conf.d"
The second entry replaces the entire contents of /etc/default/kubelet. If your cluster profile or user data already
sets KUBELET_EXTRA_ARGS, add --config-dir=/etc/kubernetes/kubelet.conf.d to the existing value instead of
overwriting the file, otherwise you lose the arguments already in place.
Provision or upgrade the cluster as you normally would. This prevents the issue on both airgap and connected clusters, and you do not need the node-level steps described in Restore Nodes on an Affected Cluster.
Enabling the preset, or adding the override, in the cluster profile of a cluster that is already running does not resolve the issue on that cluster, because re-applying the profile does not regenerate the live Kubelet configuration on existing nodes. For a cluster that is already affected, use the steps in Restore Nodes on an Affected Cluster instead.
Restore Nodes on an Affected Cluster
If a cluster is already reporting ImagePullBackOff, use the following steps on each affected node. These steps are a
temporary, per-node mitigation.
-
Log in to the affected node as a user with root privileges.
-
Confirm that the image is already present on the node. Replace
<image-name>with the name of the affected image, and<image-reference>with the full image reference, including the registry and tag.crictl images | grep <image-name>
crictl inspecti <image-reference> -
List the image pull records.
ls /var/lib/kubelet/image_manager/pulled/ -
Inspect each record and identify the one that references the digest of the affected image and contains no
credentialMappingfield. Replace<record-file-name>with the name of each file you inspect.cat /var/lib/kubelet/image_manager/pulled/<record-file-name> -
Remove the record you identified in the previous step.
rm /var/lib/kubelet/image_manager/pulled/<record-file-name>warningRemove only records that contain no
credentialMappingfield and that belong to the affected image. Records for other images, such as MetalLB, may contain a validcredentialMapping, and removing those can cause the corresponding images to fail. -
Create the Kubelet configuration drop-in file and set its permissions.
- K3s
- RKE2
- PXK-E
mkdir --parents /var/lib/rancher/k3s/agent/etc/kubelet.conf.d
tee /var/lib/rancher/k3s/agent/etc/kubelet.conf.d/10-image-pull-creds.conf << 'EOF'
apiVersion: kubelet.config.k8s.io/v1beta1
kind: KubeletConfiguration
featureGates:
  KubeletEnsureSecretPulledImages: true
imagePullCredentialsVerificationPolicy: NeverVerify
EOF
chmod 0600 /var/lib/rancher/k3s/agent/etc/kubelet.conf.d/10-image-pull-creds.conf
mkdir --parents /var/lib/rancher/rke2/agent/etc/kubelet.conf.d
tee /var/lib/rancher/rke2/agent/etc/kubelet.conf.d/10-image-pull-creds.conf << 'EOF'
apiVersion: kubelet.config.k8s.io/v1beta1
kind: KubeletConfiguration
featureGates:
KubeletEnsureSecretPulledImages: true
imagePullCredentialsVerificationPolicy: NeverVerify
EOF
chmod 0600 /var/lib/rancher/rke2/agent/etc/kubelet.conf.d/10-image-pull-creds.confPXK-E needs a second command that K3s and RKE2 do not, because its Kubelet does not read the drop-in directory unless you set the
--config-dirargument.mkdir --parents /etc/kubernetes/kubelet.conf.d
tee /etc/kubernetes/kubelet.conf.d/10-image-pull-creds.conf << 'EOF'
apiVersion: kubelet.config.k8s.io/v1beta1
kind: KubeletConfiguration
featureGates:
KubeletEnsureSecretPulledImages: true
imagePullCredentialsVerificationPolicy: NeverVerify
EOF
chmod 0600 /etc/kubernetes/kubelet.conf.d/10-image-pull-creds.confAdd the
--config-dirargument to/etc/default/kubelet. If the file already setsKUBELET_EXTRA_ARGS, append the argument to the existing value rather than replacing the line.echo 'KUBELET_EXTRA_ARGS="--config-dir=/etc/kubernetes/kubelet.conf.d"' > /etc/default/kubelet
chmod 0644 /etc/default/kubelet -
Restart Kubelet on the node and wait for the node to report a
Readystatus. Replace<node-name>with the name of the node.- K3s
- RKE2
- PXK-E
systemctl restart k3s
kubectl wait --for=condition=Ready node/<node-name> --timeout=300s
On a control plane node, restart the
rke2-serverservice. On a worker node, restart therke2-agentservice instead.systemctl restart rke2-server
kubectl wait --for=condition=Ready node/<node-name> --timeout=300ssystemctl restart kubelet
kubectl wait --for=condition=Ready node/<node-name> --timeout=300s -
Delete the affected pods so that they are rescheduled and use the local image. Replace
<cluster-namespace>with the namespace of your cluster. Delete any other pods that remain in anImagePullBackOffstatus as well.kubectl delete pod --namespace palette-system --selector app=palette-webhook
kubectl delete pod --namespace <cluster-namespace> --selector control-plane=palette-lite-controller-manager -
Confirm that the pods recover. The pod events should include a message stating that the image is already present on the machine, and the pods should reach a
Runningstatus.kubectl get pods --namespace palette-system --selector app=palette-webhook
kubectl get events --namespace palette-system --sort-by=.lastTimestamp | grep palette-webhook -
Confirm that the webhook service endpoints point to the new pod.
kubectl get endpoints --namespace palette-system palette-webhook-serviceIf the cluster was left in a partially upgraded state with a broken CRD conversion webhook, wait until the webhook endpoints are healthy before you resume any control plane or cluster profile operations. Confirm that the cluster resources are readable first. Replace
<cluster-namespace>with the namespace of your cluster.kubectl get spc --namespace <cluster-namespace>
Verification
Whether you enabled the preset, applied the values override, or ran the node-level steps, verify that the setting is in
effect. Replace <node-name> with the name of the node.
kubectl get --raw "/api/v1/nodes/<node-name>/proxy/configz" | jq '.kubeletconfig.imagePullCredentialsVerificationPolicy'
"NeverVerify"
If the command returns NeverVerifyPreloadedImages, the setting has not reached the running Kubelet, and the node is
still exposed to the issue.
Scenario - Edge Host Reset Fails with Encrypted Persistent Partition
Edge hosts using encrypted persistent partitions may fail to complete a reset. A limitation in Kairos version 3.5.3 prevents these partitions from being reinitialized during the reset workflow, resulting in the operation stopping prematurely.
To address this issue, override the default reset behavior by supplying a custom before-reset stage through the user
data. This ensures that the persistent partition is reformatted correctly before the reset workflow continues.
Add the following configuration to the user-data file for the affected Edge host.
#cloud-config
reset:
  reset-persistent: false
stages:
  before-reset:
    - name: "reset persistent"
      commands:
        - |
          #!/bin/bash
          udevadm trigger --subsystem-match=block
          udevadm trigger --type=all || udevadm trigger
          udevadm settle
          if [ -e /dev/disk/by-label/COS_PERSISTENT ]; then
            echo "Persistent partition found"
          else
            echo "Persistent partition not found"
            exit 0
          fi

          # umount persistent partition
          umount /dev/disk/by-label/COS_PERSISTENT || true

          # format persistent partition
          mkfs.ext4 /dev/disk/by-label/COS_PERSISTENT -L COS_PERSISTENT
Scenario - Velero Restore Fails with runAsNonRoot Validation Error
This issue was resolved in Palette version 4.8.21.
On Edge Native clusters, restores of security-hardened applications (such as Argo CD) may fail with the affected
application pods stuck in the Init:CreateContainerConfigError state, showing
Error: container has runAsNonRoot and image has non-numeric user (cnb), cannot verify user is non-root on the
restore-wait init container.
This occurs because Velero is configured by default with --default-volumes-to-fs-backup=true on Edge Native clusters.
During a restore, Velero injects a restore-wait init container that uses the image velero-restore-helper. That image
runs as a non-numeric user cnb, while the restored workload (for example, Argo CD) has a security context that
includes runAsNonRoot: true but lacks an explicit numeric runAsUser. Kubernetes cannot verify that the user cnb is
non-root without a numeric user ID, so it blocks the container from starting. As a result, the restore process remains
stuck waiting for pod volume restores to complete.
Debug Steps
To resolve this issue, explicitly configure numeric non-root IDs for the user, group, and filesystem group for affected applications before taking backups.
-
Log in to Palette.
-
From the left main menu, select Profiles. Then select the profile of your cluster.
-
Select the application whose restore failed (for example, Argo CD). Under Pack Details, choose Values to display the
values.yamlfile. -
Add the following lines under
global.securityContext.global:
securityContext:
runAsUser: 999
runAsGroup: 999
fsGroup: 999This configuration ensures Kubernetes can verify that the pod runs as a non-root user and allows the
restore-waitcontainer to start successfully during restores. -
Save the changes as a new version of the cluster profile and update your cluster to use the updated profile. For more information, refer to Update a Cluster.
-
Create a new cluster backup, then restore it. For more information, refer to Create Cluster Backup and Restore Cluster Backup.
Scenario - CoreDNS Pods Stuck in CrashLoopBackOff Due to DNS Loop
On Edge clusters whose hosts run Ubuntu 24.04 with a Unified Kernel Image (UKI), CoreDNS pods may enter the
CrashLoopBackOff state with logs showing the following error.
[FATAL] plugin/loop: Loop (127.0.0.1:<ephemeral-port> -> :53) detected for zone "."...
This happens because /etc/resolv.conf is symlinked to /run/systemd/resolve/stub-resolv.conf, which lacks real DNS
server entries and points to the local systemd stub 127.0.0.53. Both 127.0.0.1 and 127.0.0.53 are localhost
addresses, meaning they only communicate within the host and cannot access external DNS servers. As a result, CoreDNS
forwards DNS queries to itself, creating a recursive loop.
Debug Steps
-
Issue the following command to view the
/run/systemd/resolve/resolv.conffile content.cat /run/systemd/resolve/resolv.conf -
Verify that it lists at least one nameserver entry pointing to a real, reachable DNS server (not
nameserver 127.0.0.53ornameserver 127.0.0.1). -
Open CoreDNS ConfigMap.
kubectl -n kube-system edit configmap coredns -
Replace
forward . /etc/resolv.confwithforward . /run/systemd/resolve/resolv.confif this file contains at least one nameserver other thannameserver 127.0.0.53ornameserver 127.0.0.1. Alternatively, if your environment maintains another resolver file containing real DNS servers, use that file path instead. -
Issue the following command to restart CoreDNS pods.
kubectl -n kube-system rollout restart deployment coredns
This will resolve the issue, ensuring CoreDNS and cluster DNS services operate as expected.
Scenario - content-length: 0 Errors during Content Synchronization
Unintended or non-graceful reboots during content bundle push operations can cause inconsistency in the primary
registry, resulting in 0-byte blob files and subsequent content-length: 0 errors during content synchronization.
When operating a locally managed cluster, if you observe the content-length: 0 error during content sync, follow the
steps below to verify whether the error was caused by an inconsistency in the primary registry and to fix the issue.
Debug Steps
-
Issue the following command and observe if there are files that are zero bytes in size.
ls -la /usr/local/spectrocloud/peerbundle/sha256/If you observe output similar to the following, where the file size is zero, proceed to the next step.
-rw------- 1 root root 0 Aug 11 01:52 /usr/local/spectrocloud/peerbundle/sha256 -
Issue the following command to remove all files with zero size.
sudo find /usr/local/spectrocloud/peerbundle/sha256/ -type f -size 0 -delete -
Restart the Palette agent service and verify that it is active.
sudo systemctl restart spectro-stylus-agent.service
sudo systemctl status spectro-stylus-agent.service
This will resolve the issue and content sync will proceed normally.
Scenario – PXK-E Clusters on RHEL and Rocky 8 Fail Kubernetes Initialization
Palette eXtended Kubernetes - Edge (PXK-E) clusters
running Kubernetes v1.32.x or later on RHEL or Rocky Linux 8.x may experience failure during Kubernetes initialization.
This occurs because RHEL and Rocky 8.x come with kernel version 4.18.x, which does not meet the
kubeadm system requirements introduced in Kubernetes
v1.32.x. You can observe the following error in kube-init logs.
[ERROR SystemVerification]: kernel release 4.18.0-553.16.1.el8_10.x86_64 is unsupported. Recommended LTS version from the 4.x series is 4.19. Any 5.x or 6.x versions are also supported. For cgroups v2 support, the minimal version is 4.15 and the recommended version is 5.8+...
There are several possible ways to troubleshoot this issue:
- Rebuild the OS using RHEL or Rocky Linux 9.x, as they come with kernel 5.14+ by default.
- Update the kernel version to 4.19 or later in the 4.x series, or to any 5.x or 6.x version.
To view all available versions of the kernel-lt (long-term support) package from ELRepo, run the following command on
a system that uses dnf, such as RHEL, Rocky Linux, CentOS, or a compatible container.
dnf --showduplicates --enablerepo=elrepo-kernel list available kernel-lt
Debug Steps - Update the Kernel Version
Limitations
- Appliance mode is supported only for RHEL-based images and is not supported for Rocky Linux.
Debug Steps - Update the Kernel Version for Appliance Mode
-
Customize the
Dockerfilein theCanvOSdirectory. Find the conditional block for RHEL.RUN if [ "${OS_DISTRIBUTION}" = "rhel" ]; then \
cp -a /certs/. /etc/pki/ca-trust/source/anchors/ && \
update-ca-trust; \
fiUpdate the conditional block as in the example below to install the latest available version in the 5.4.x Long-Term Support (LTS) kernel line using ELRepo.
RUN if [ "${OS_DISTRIBUTION}" = "rhel" ]; then \
    cp --archive /certs/. /etc/pki/ca-trust/source/anchors/ && \
    update-ca-trust && \
    dnf install --assumeyes https://www.elrepo.org/elrepo-release-8.el8.elrepo.noarch.rpm && \
    dnf update --assumeyes && \
    dnf --enablerepo=elrepo-kernel install --assumeyes kernel-lt kernel-lt-modules-extra && \
    dnf clean all; \
    fi
Alternatively, you can update the conditional block as in the example below to pin an exact version. Replace
5.4.261-1.el8.elrepowith the required version.RUN if [ "${OS_DISTRIBUTION}" = "rhel" ]; then \
cp --archive /certs/. /etc/pki/ca-trust/source/anchors/ && \
update-ca-trust && \
dnf install --assumeyes https://www.elrepo.org/elrepo-release-8.el8.elrepo.noarch.rpm && \
dnf update --assumeyes && \
dnf --enablerepo=elrepo-kernel install --assumeyes \
kernel-lt-5.4.261-1.el8.elrepo \
kernel-lt-modules-extra-5.4.261-1.el8.elrepo && \
dnf clean all; \
fi -
Rebuild the ISO and provider image and redeploy the cluster.
-
After the deployment is complete, issue the following command on the node to ensure you updated the kernel version to a supported one.
uname --kernel-release
Debug Steps - Update the Kernel Version for Agent Mode
-
Install the latest available version in the 5.4.x LTS kernel line using ELRepo. Establish an SSH connection to the PXK-E node and issue the following commands.
dnf install --assumeyes https://www.elrepo.org/elrepo-release-8.el8.elrepo.noarch.rpm
dnf update --assumeyes
dnf --enablerepo=elrepo-kernel install --assumeyes kernel-lt kernel-lt-modules-extra
reboot
Alternatively, you can issue the following command to pin an exact version. Replace
5.4.261-1.el8.elrepowith the required version.dnf install --assumeyes https://www.elrepo.org/elrepo-release-8.el8.elrepo.noarch.rpm
dnf update --assumeyes
dnf --enablerepo=elrepo-kernel install --assumeyes \
kernel-lt-5.4.261-1.el8.elrepo \
kernel-lt-modules-extra-5.4.261-1.el8.elrepo
reboot -
Issue the following command after the reboot to ensure you updated the kernel version to a supported one.
uname --kernel-release
Scenario - PXK-E Clusters in VerteX Deployments Experience Failure upon Reboot
When rebooting control plane nodes in Palette eXtended Kubernetes - Edge (PXK-E) clusters
deployed via VerteX, the kube-vip component may fail to start due to early DNS resolution issues. You can observe
repeated errors in the system logs using journalctl --unit=kubelet.
E0619 21:53:53.613367       1 leaderelection.go:327] error retrieving resource lock kube-system/plndr-cp-lock: Get "https://kubernetes:6443/apis/coordination.k8s.io/v1/namespaces/kube-system/leases/plndr-cp-lock": dial tcp: lookup kubernetes on 10.10.128.8:53: no such host
E0619 21:54:00.647219       1 leaderelection.go:327] error retrieving resource lock kube-system/plndr-cp-lock: Get "https://kubernetes:6443/apis/coordination.k8s.io/v1/namespaces/kube-system/leases/plndr-cp-lock": dial tcp: lookup kubernetes on 10.10.128.8:53: no such host
Although DNS becomes available shortly after boot, kube-vip does not recover automatically. To fix this, stop and
remove the container manually. The Kubelet then restarts the component using the current system state.
Debug Steps
-
On each control plane node, list all operating
kube-vipcontainers using thecrictltool.crictl ps 2>/dev/null | grep kube-vip | awk '{print $1}' -
Stop and remove each container.
crictl stop <container-id> && crictl rm <container-id>
Scenario - Canonical Edge Clusters in Proxied Environments Experience Failure upon Reboot
When rebooting nodes in an Edge cluster using Palette Optimized Canonical deployed in a proxied environment, the nodes
may fail to come back online. To prevent this, add the second IP address in the service_cidr range from the Canonical
pack to the NO_PROXY list in your Edge installer user-data.
Debug Steps
-
Log in to Palette.
-
From the left Main Menu, select Profiles. Then select the profile you will use to deploy your cluster.
-
Select the Kubernetes layer, the
Palette Optimized Canonicalpack. Click values.yaml to view the values. -
Take note of the
service_cidrvalue inpack.cluster.config. -
Add the second IP of the CIDR block in the
service_cidrrange to thestylus.site.network.noProxyparameter. For example, if yourservice_cidris192.169.0.0/16, you need to add192.169.0.1to the parameter.Example#cloud-config
stylus:
site:
paletteEndpoint: api.spectrocloud.com
edgeHostToken: <yourRegistrationToken>
projectName: edge-sites
tags:
city: chicago
building: building-1
zip-code: 95135
network:
httpProxy: http://proxy.example.com
httpsProxy: https://proxy.example.com
noProxy: 10.10.128.10,10.0.0.0/8,192.169.0.1
nameserver: 1.1.1.1
Scenario - Cilium Pod Stuck During Kubernetes Upgrade Due to nsenter Permission Issue
During a Kubernetes upgrade, the Cilium pod may get stuck in the Init:CrashLoopBackoff state due to nsenter permission
issues. To address the issue, patch the cilium DaemonSet with the specified annotations.
Debug Steps
-
Connect to your cluster via
kubectl. -
Issue the following command to edit the DaemonSet.
kubectl --namespace kube-system edit ds cilium -
Add the following annotations to the DaemonSet.
spec:
  template:
    metadata:
      annotations:
        container.apparmor.security.beta.kubernetes.io/cilium-agent: "unconfined"
        container.apparmor.security.beta.kubernetes.io/mount-cgroup: "unconfined"
        container.apparmor.security.beta.kubernetes.io/clean-cilium-state: "unconfined"
        container.apparmor.security.beta.kubernetes.io/apply-sysctl-overwrites: "unconfined"
Scenario - Cluster Creation Failure Due to Nodeadm not Found
When attempting to deploy a cluster with Palette eXtended Kubernetes - Edge (PXK-E)
and agent mode on Palette agent version 4.5.14, adding a custom stylus.path to
the user-data file causes cluster creation to fail as it cannot find
kubeadm. A custom stylus.path can be added during the
Install Palette Agent steps.
Refer to Identify the Latest Palette Agent Version for guidance in retrieving your Palette agent version number.
To resolve this scenario, add a cloud-init stage to your BYOS Edge OS pack configuration by following the debug steps below.
Debug Steps
-
Log in to Palette.
-
From the left Main Menu, select Profiles.
-
On the Profiles page, find and click on your cluster profile.
-
Select the OS layer of your cluster profile.
-
Click Values in the Pack Details section. In the YAML editor, add the following entry.
stages:
  initramfs:
    - name: "Workaround for kubeadm path issue in Palette agent v4.5.14"
      if: "[ ! -f /usr/bin/kubeadm ]"
      commands:
        - cp <customStylusPath>/usr/bin/kubeadm /usr/bin/
        - reboot now
Replace
<customStylusPath>with the customstylus.pathyou provided in the user-data file during the Install Palette Agent steps, as demonstrated in the following example.pack:
content:
images:
- image: "{{.spectro.pack.edge-native-byoi.options.system.uri}}"
options:
---
stages:
initramfs:
- name: "Workaround for kubeadm path issue in Palette agent v4.5.14"
if: "[ ! -f /usr/bin/kubeadm ]"
commands:
- cp /persistent/spectro/usr/bin/kubeadm /usr/bin/
- reboot now -
Click Confirm Updates to save your changes.
-
Click Save Changes on the cluster profile page.
-
Deploy your cluster using the updated cluster profile.
Scenario - IP Address not Assigned to Edge Host
When you add a new VMware vSphere Edge host to an Edge cluster, the IP address may fail to be assigned to the Edge host after a reboot.
Debug Steps
-
Access the Edge host through the vSphere web console.
-
Issue the following command.
networkctl reloadThis command restarts the Edge host network and allows the Edge host to receive an IP address.
Scenario - Override or Reconfigure Read-only File System Stage
If you need to override or reconfigure the read-only file system, you can do so using the following steps.
Debug Steps
-
Power on the Edge host.
-
Press the keyboard key
Eafter highlighting the menu ingrubmenu. -
Type
rd.cos.debugrwand pressEnter.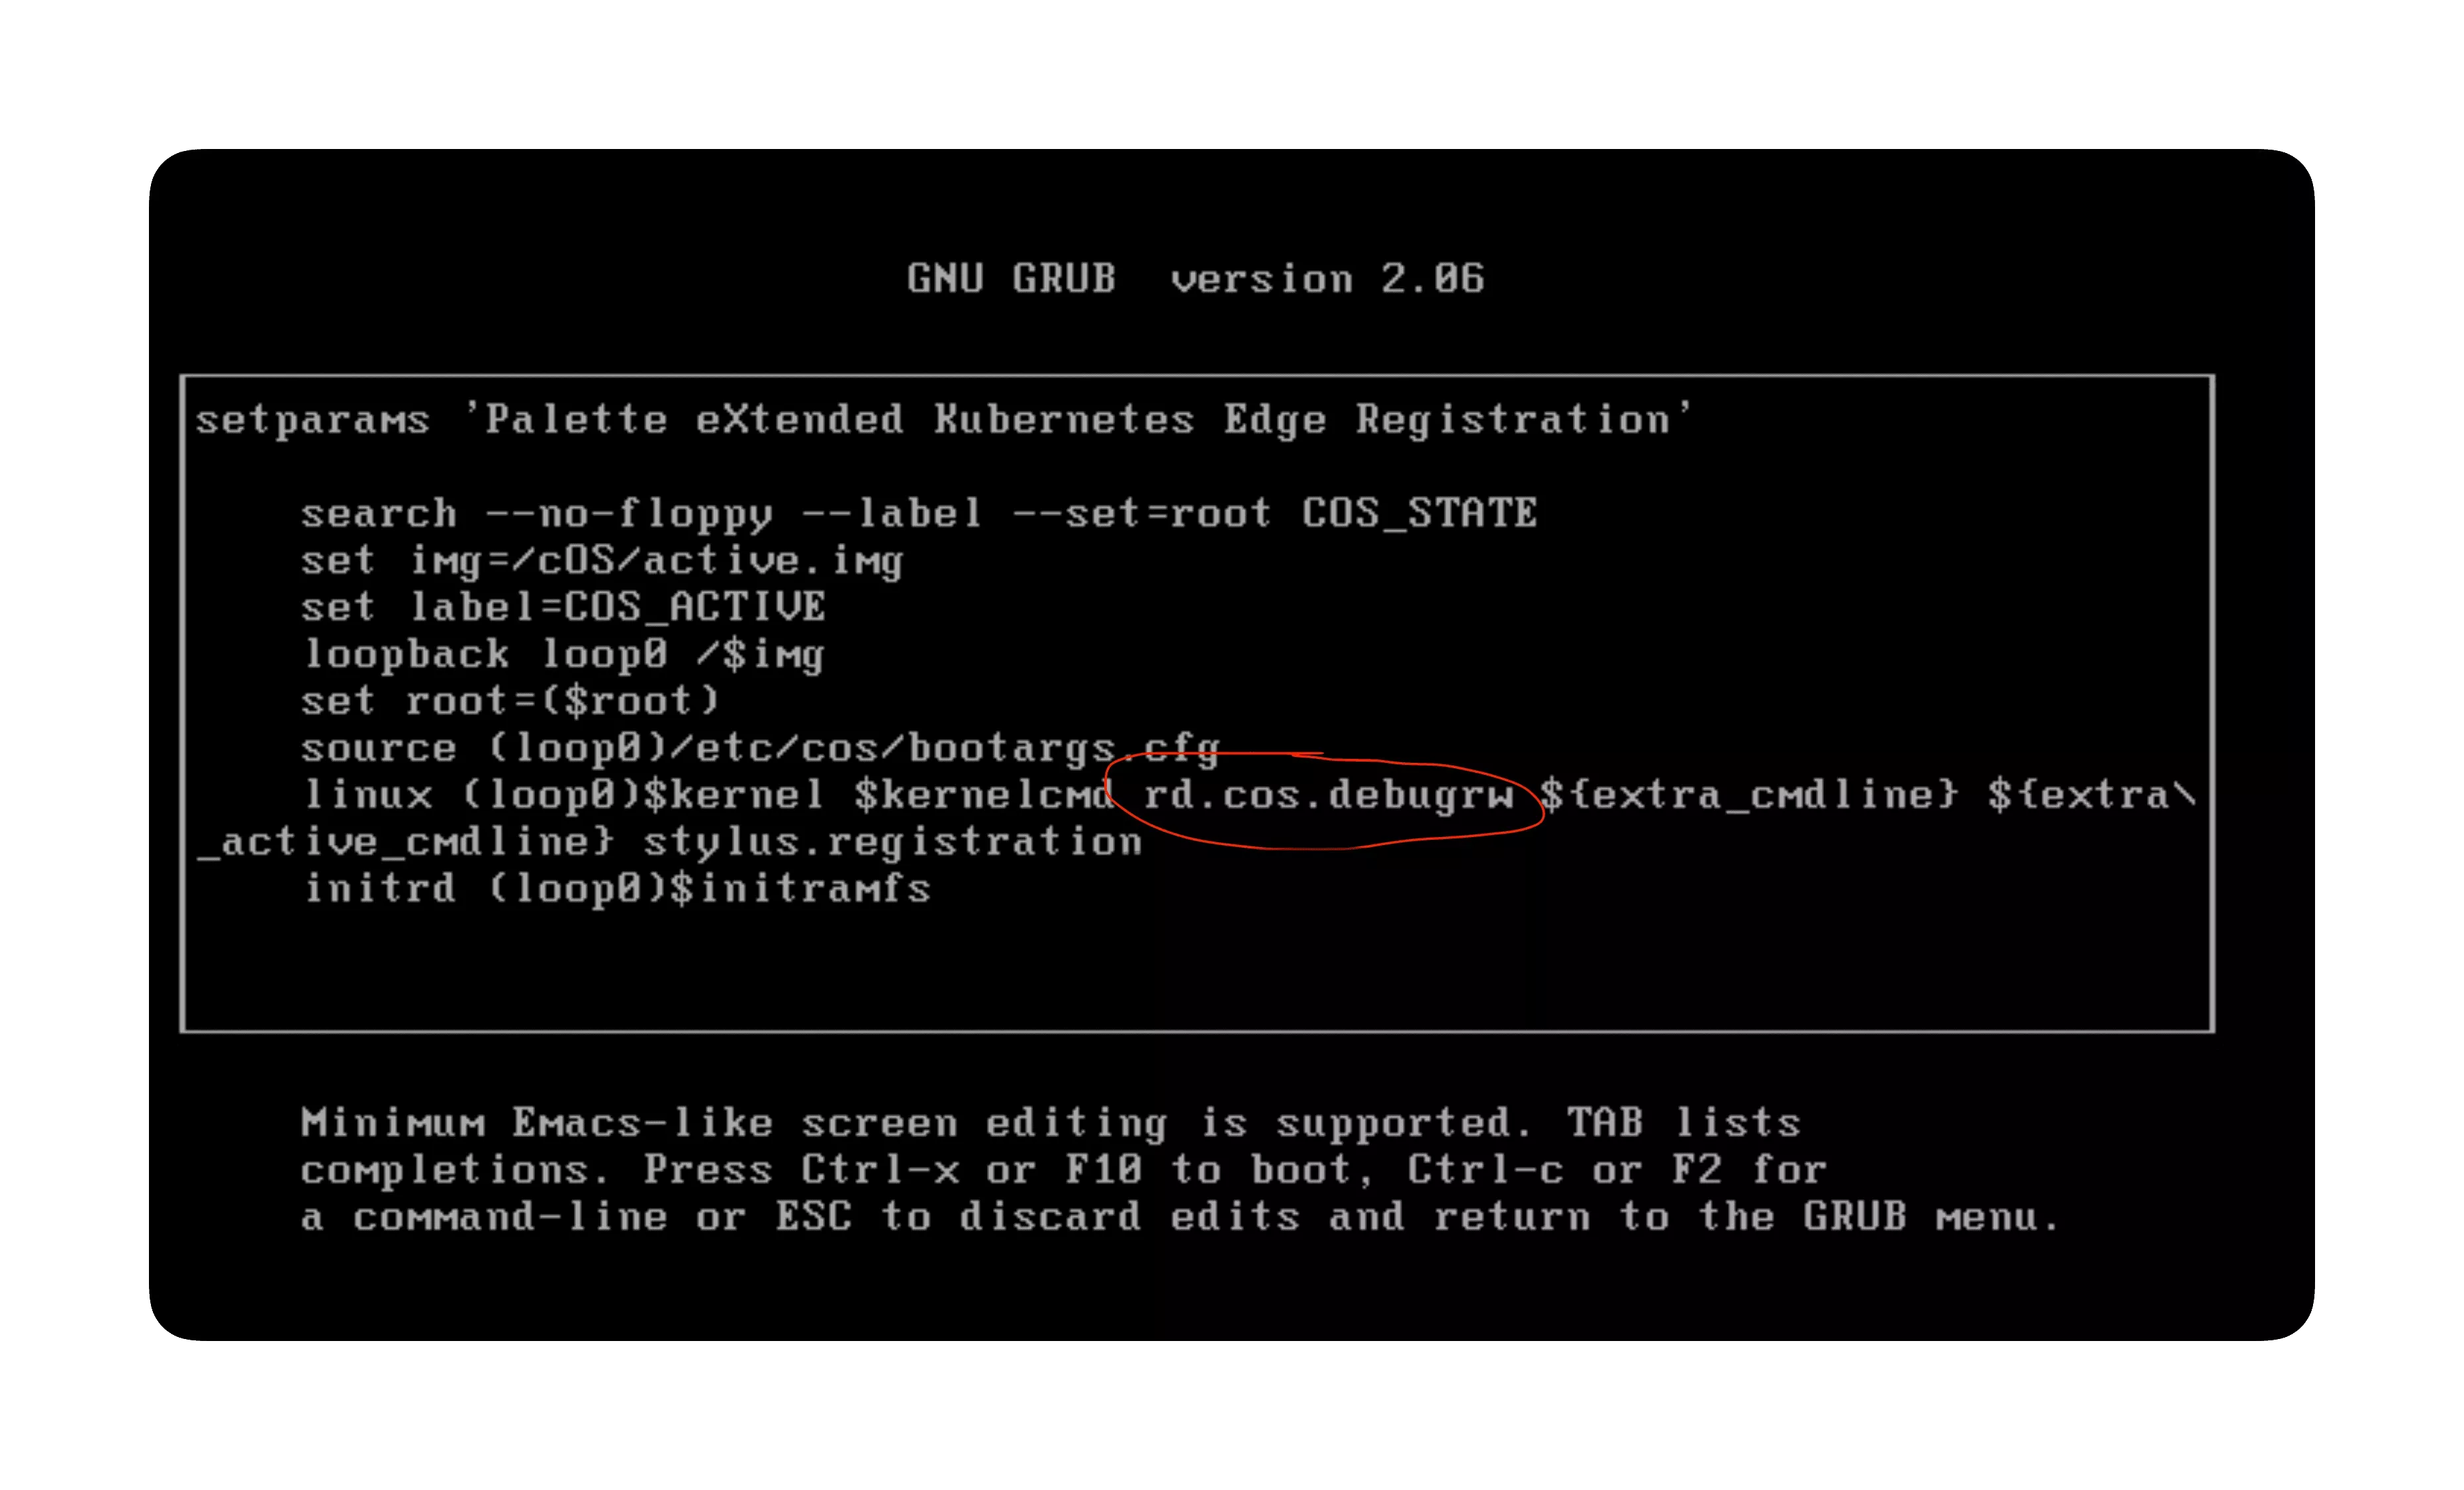
-
Press the keys CTRL + X to boot the system.
-
Make the required changes to the image.
-
Reboot the system to resume the default read-only file system.
Scenario - Pod State Unknown After Reboot with Overlay Network Enabled
On slower networks, it's possible that this is due to KubeVip leader election timeouts. To debug, you can manually adjust the values of related environment variables in the KubeVip DaemonSet with the following steps.
Debug Steps
-
Ensure you can access the cluster using kubectl. For more information, refer to Access Cluster with CLI.
-
Issue the following command:
kubectl edit ds kube-vip-ds --namespace kube-system -
In the
envof the KubeVip service, modify the environment variables to have the following corresponding values.env:
- name: vip_leaderelection
value: "true"
- name: vip_leaseduration
value: "30"
- name: vip_renewdeadline
value: "20"
- name: vip_retryperiod
value: "4" -
Within a minute, the old Pods in unknown state will be terminated and Pods will come up with the updated values.
Scenario - Palette Webhook Pods Fail to Start
If the Palette webhook pods fail to start, it may be due to the palette-lite-controller-manager pods encountering issues or not being available. Use the following steps to troubleshoot and resolve the issue.
Debug Steps
-
Ensure you can access the Kubernetes cluster using kubectl. For more information, refer to Access Cluster with CLI.
-
Open up a terminal session and issue the following command to check the status of the palette-lite-controller-manager pods.
kubectl get pods --all-namespaces | grep palette-lite-controller-managercluster-661acf1dfc746f8217de2712 palette-lite-controller-manager-6856746c8-7p9k2 2/2 Running 0 6mIf the pods are active and available with an age greater than five minutes, then the issue may be with the Palette webhook. Proceed to the next step.
infoIf the pods are not active, use the command
kubectl describe pod <pod-name> --namespace palette-systemto check the pod logs for more information about why the pods are not starting. Replace<pod-name>with the name of the pod that is not starting. Scroll down to theEventssection to view the logs. You can try to delete the pod and check if it starts successfully. If the issue persists, contact our support team by emailing. -
Check the status of the Palette webhook pods. Use the following command to verify the status.
kubectl get pods --namespace palette-systemNo resources found in palette-system namespaceIf the output displays a message stating No resources found in palette-system namespace then the lacking Palette webhook pods are the issue for the cluster not starting.
-
Delete all existing palette-lite-controller-manager pods using the following commands.
export NAMESPACE=$(kubectl get pods --all-namespaces | grep palette-lite-controller-manager | awk '{print $1}')
export PALETTE_POD_NAME=$(kubectl get pods --all-namespaces | grep palette-lite-controller-manager | awk '{print $2}')
kubectl delete pod $PALETTE_POD_NAME --namespace $NAMESPACE -
After a few seconds, verify that the palette-lite-controller-manager pods are active and available.
kubectl get pods --all-namespaces | grep palette-lite-controller-manager -
Check the status of the Palette webhook pods. A successful output should display the status of the palette-webhook pods.
kubectl get pods --namespace palette-systemNAME READY STATUS RESTARTS AGE
palette-webhook-548c55568c-p74zz 1/1 Running 0 2m -
If you continue to encounter issues, contact our support team by emailing support@spectrocloud.com so that we can provide you with further guidance.
Scenario - systemd-resolved.service Enters Failed State
When you create a cluster with an Edge host that operates the Red Hat Enterprise Linux (RHEL) and Ubuntu Operating
Systems (OS), you may encounter an error where the systemd-resolved.service process enters the failed state. This
prevents the nameserver from being configured, which will result in cluster deployment failure.
Debug Steps
-
Establish an SSH connection to the Edge host.
Alternatively, press the keys FN + CTRL + CMD + F1 on a keyboard that is connected to the Edge host to log in to the terminal. If you are on Windows, press FN + CTRL + ALT + F1.
-
Issue the following command.
chmod a+rwxt /var/tmp
systemctl enable --now systemd-resolved.service
This will start the
systemd-resolved.serviceprocess and move the cluster creation process forward.
Scenario - Degraded Performance on Disk Drives
If you are experiencing degraded performance on disk drives, such as Solid-State Drive or Nonvolatile Memory Express drives, and you have Trusted Boot enabled. The degraded performance may be caused by TRIM operations not being enabled on the drives. TRIM allows the OS to notify the drive which data blocks are no longer in use and can be erased internally. To enable TRIM operations, use the following steps.
Debug Steps
-
Log in to Palette.
-
Navigate to the left Main Menu and click on Profiles.
-
Select the Cluster Profile that you want to use for your Edge cluster.
-
Click on the BYOOS layer to access its YAML configuration.
-
Add the following configuration to the YAML to enable TRIM operations on encrypted partitions.
stages:
  boot.after:
    - name: Ensure encrypted partitions can be trimmed
      commands:
        - |
          DEVICES=$(lsblk -p -n -l -o NAME)
          if cat /proc/cmdline | grep rd.immucore.uki; then TRUSTED_BOOT="true"; fi
          for part in $DEVICES
          do
            if cryptsetup isLuks $part; then
              echo "Detected encrypted partition $part, ensuring TRIM is enabled..."
              if ! cryptsetup status ${part#/dev/} | grep discards; then
                echo "TRIM is not enabled on $part, enabling TRIM..."
                if [ "$TRUSTED_BOOT" = "true" ]; then
                  cryptsetup refresh --allow-discards --persistent ${part#/dev/}
                else
                  if cryptsetup status ${part#/dev/} | grep LUKS2; then OPTIONS="--persistent"; fi
                  passphrase=$(echo '{ "data": "{ \"label\": \"LABEL\" }"}' | /system/discovery/kcrypt-discovery-challenger "discovery.password" | jq -r '.data')
                  echo $passphrase | cryptsetup refresh --allow-discards $OPTIONS ${part#/dev/}
                fi
                if [ "$?" = "0" ]; then
                  echo "TRIM is now enabled on $part"
                else
                  echo "TRIM coud not be enabled on $part!"
                fi
              else
                echo "TRIM is already enabled on $part, nothing to do."
              fi
            fi
done -
Click on Confirm Updates to save the changes.
-
Use the updated profile to create a new Edge cluster or update an existing Edge cluster.
Scenario - Clusters with Cilium and RKE2 Experiences Kubernetes Upgrade Failure
When you upgrade your cluster from RKE2 1.29 to 1.30 and your cluster uses the Cilium Container Network Interface (CNI), the upgrade could fail with error messages similar to the following. This is due to an upstream issue. You can fix this issue by adding a few annotations to the Cilium DaemonSet.
Debug Steps
-
Connect to your cluster using kubectl. For more information, refer to Access Cluster with kubectl.
-
Issue the following command from the terminal edit the Cilium DaemonSet.
kubectl edit ds cilium --namespace kube-system -
Under
metadata.annotations, add the following annotations.metadata:
annotations:
deprecated.daemonset.template.generation: "1"
meta.helm.sh/release-name: cilium-cilium
meta.helm.sh/release-namespace: kube-system
container.apparmor.security.beta.kubernetes.io/cilium-agent: "unconfined"
container.apparmor.security.beta.kubernetes.io/clean-cilium-state: "unconfined"
container.apparmor.security.beta.kubernetes.io/mount-cgroup: "unconfined"
container.apparmor.security.beta.kubernetes.io/apply-sysctl-overwrites: "unconfined"
Download Node Logs from Edge Clusters
If you experience issues with your Edge cluster control plane or workloads, you can download the logs of your cluster nodes to help investigate the root cause as long as your cluster is in Healthy status.
The downloaded log archive includes the following systemd service log files as well as other log files related to the Palette agent:
- stylus-agent.service
- stylus-operator.service
- spectro-stylus-agent.service
- spectro-stylus-operator.service
- k3s.service
- k3s-agent.service
- rke2.service
- rke2-agent.service
- /var/log/stylus-upgrade.log
- /var/log/stylus-upgrade-script.log
- /var/log/stylus-init-upgrade.log
- /var/log/kube-init.log
- /var/log/kube-join.log
- /var/log/kube-upgrade.log
- /var/log/kube-post-init.log
- /proc/cmdline
Debug Steps
-
Log in to Palette.
-
Navigate to the left Main Menu and click on Clusters.
-
Select the cluster whose logs you want to download.
-
In the upper-right corner of the cluster page, click Settings.
-
In the drop-down Menu that appears, click Download Logs.
-
Check the Node Logs box and click Download. You may also download logs from other components at the same time.
Scenario - Kubelet Process Cannot Access kubeadm-flags
If using the FIPS version of Agent Mode on a Rocky Linux edge host, SELinux may incorrectly label the kubeadm-flags.env file during cluster deployment or when certain configurations are adjusted, preventing the Kubelet from accessing it and properly managing the cluster. To resolve this issue, reset the SELinux context of the Kubelet environment variable to its default state based on SELinux policy rules.
Debug Steps
-
After deploying the cluster, monitor the Kubelet status.
systemctl status kubelet -
Check the logs for messages related to SELinux denials and kubeadm-flags.env.
ausearch -message avc --start recent | grep kubeadm-flags.envThe following output indicates that SELinux security policies are denying read operations attempted by the Kubelet.
time->Wed Jan 17 14:32:01 2025
type=AVC msg=audit(1673968321.452:456): avc: denied { read } for pid=1234 comm="kubelet" name="kubeadm-flags.env" dev="sda1" ino=56789 scontext=system_u:system_r:kubelet_t:s0 tcontext=unconfined_u:object_r:default_t:s0 tclass=file permissive=0 -
Reset the SELinux context of the Kubelet environment variable to its default state.
restorecon -v /var/lib/kubelet/kubeadm-flags.env -
Restart the Kubelet to apply your changes.
systemctl restart kubelet
Scenario - Agent Mode Deployments CNI Folder Permission Issues
Agent mode clusters that use PKX-E as the Kubernetes layer have the contents of the /opt/cni/bin folder set
incorrectly. This prevents the CNI that do not run as root, such as Cilium, from operating.
Debug Steps
-
Log in to Palette.
-
Navigate to the left Main Menu and click on Profiles.
-
Click on the profile used by your agent mode cluster.
-
In the OS pack of your agent mode cluster profile, configure the following cloud-init stages. The same commands are executed in multiple stages to ensure that they take effect.
stages:
boot.before:
   - name: "Ensure CNI directory permissions on restart"
      if: '[ -d /opt/cni/bin ]'
      commands:
      - chown root:root -R /opt/cni/bin
boot:
   - name: "Ensure CNI directory permissions on restart"
      if: '[ -d /opt/cni/bin ]'
      commands:
      - chown root:root -R /opt/cni/bin
boot.after:
   - name: "Ensure CNI directory permissions on restart"
      if: '[ -d /opt/cni/bin ]'
      commands:
- chown root:root -R /opt/cni/bin -
Save the changes as a new version of the cluster profile and update your agent mode cluster to use the updated profile. For more information, refer to Update a Cluster.
Scenario - Shared Volumes Fail on Kernel 7.x Due to NFSv4.1 Directory Delegations
On Edge clusters running Linux kernel 6.19 or later, shared Read-Write-Many (RWX) volumes served by an older NFS server
fail to open with a remote I/O error (EREMOTEIO). Both the Longhorn share manager and the Piraeus RWX driver ship an
NFS server that is affected. Kernels known to trigger the issue include Hadron 7.1.3 and Ubuntu 7.0.0-generic, which
is the kernel that Ubuntu 24.04 hosts pull in when UPDATE_KERNEL=true or a 7.x kernel pack is applied. Pre-6.19
kernels such as stock Ubuntu 6.8 and RHEL 9 do not trigger the issue. Block, hostPath, Rook RBD, Rook CephFS, Ceph CSI
RBD, Local Path Provisioner, Portworx, Hitachi HSPC, NetApp Trident, HPE CSI, and KubeVirt CSI volumes are also
unaffected because they do not depend on the affected NFS server.
Symptoms include:
- The in-cluster Zot registry enters a
CrashLoopBackOffstate because it cannot read its Longhorn shared volume. - Image pulls from the registry VIP fail with
connection refusedorImagePullBackOff. - Kubernetes upgrades hang because the shared volume is broken at the NFS layer, and rebooting the node does not recover.
Linux kernel 6.19 and later enable NFSv4.1 directory delegations by default and send an optional GET_DIR_DELEGATION
operation as part of each directory open. An NFS server that does not implement directory delegations must reply that
the operation is not supported, so that the client retries without it. Older NFS server builds reply that the operation
is illegal instead, which the client does not retry, and the user-space application reports a remote I/O error. The disk
is fine; only the NFS handshake is wrong. This is why the same CSI pack works on stock Ubuntu 6.8 and RHEL 9 and fails
on Hadron 7.1.3 or Ubuntu 7.0.0-generic.
The durable fix is to upgrade the affected CSI pack. Use the Longhorn CSI pack
at version 1.12.0. Version 1.11.3 also contains the fix but requires Kubernetes v1.34 or later. Do not remain on
Longhorn CSI 1.8.x through 1.11.2 on kernel 6.19 or later. For Piraeus RWX, no fixed pack is available yet, so avoid
Piraeus shared RWX volumes on kernel 6.19 or later. Read-Write-Once (RWO) and DRBD volumes are unaffected.
Until you can move to a fixed pack, apply the following node-level workaround.
Debug Steps
Apply the workaround on every node that mounts the shared volume, not only on the node running the CSI share manager.
For example, if the affected workload is zot, the workaround must be present on the node hosting the zot-0 pod. Skip
the workaround on nodes running pre-6.19 kernels because those kernels do not trigger the issue.
Choose the option that matches your host configuration.
Option 1 - Set the Kernel Module Option on the Host
On Ubuntu, Hadron, and RHEL hosts with a writable /etc directory, disable NFSv4 directory delegations through a
modprobe drop-in file, then reboot the node.
-
Log in to the affected node as a user with root privileges.
-
Create the drop-in file.
sudo tee /etc/modprobe.d/nfs-nodirdelegation.conf >/dev/null <<'EOF'
options nfsv4 directory_delegations=0
EOF -
Reboot the node.
sudo reboot
On Kairos or Hadron hosts, a file written directly to /etc might be lost during the next A/B upgrade. To persist the
workaround across upgrades, apply the same drop-in through an OEM cloud-config file such as
/oem/90_nfs_workaround.yaml.
#cloud-config
stages:
  boot.before:
    - name: "disable nfsv4 directory delegations"
      files:
        - path: /etc/modprobe.d/nfs-nodirdelegation.conf
          permissions: 0644
          content: |
            options nfsv4 directory_delegations=0
Option 2 - Set the Kernel Command-Line Parameter in the UKI
On trusted-boot or Unified Kernel Image (UKI) hosts where /etc is not writable, add the following token to the kernel
command line in the UKI or EdgeForge image, then rebuild and
redeploy the UKI.
nfsv4.directory_delegations=0
Reboot the host after redeploying the UKI.
Verify the Workaround
After the node reboots, confirm that directory delegations are disabled and restart the affected workload.
-
Confirm the kernel setting.
cat /sys/module/nfsv4/parameters/directory_delegationsThe command must print
N. If thenfsv4kernel module has not been loaded yet, the file at that path is missing until something mounts NFS. The setting still applies the next time the module loads. -
Restart the affected workload. For example, restart the
zot-0pod.kubectl --namespace zot-system delete pod zot-0 -
Confirm that shared volumes mount successfully and the workload reports a healthy state.