Deploy a Model
This guide explains how to deploy a model to a running PaletteAI Inference Launchpad appliance, choose which nodes run it, and verify that the model is serving requests. On a multi-node appliance, you select the target nodes in the deploy wizard. For why you would pin a model to some nodes and not others, refer to Model Placement.
Prerequisites
- A running PaletteAI Inference Launchpad appliance, with the admin console reachable and operator access.
- At least one node that can host the model you intend to deploy, or a sharing group that the model can join. For sharing groups, refer to GPU Sharing.
- The model present in the appliance catalog and able to fit at least one node's available GPU resources. To confirm support, refer to Certified Models by Hardware and Suggested Hardware. To place a model in the appliance catalog, follow Upload a Model first.
Deploy a Model
-
From the left main menu, select Cluster. The page opens on the Nodes tab.
-
Select the Models tab, and then select Deploy Model. The Deploy a model wizard opens on the Model and placement step. The wizard's three steps are Model and placement, Serving, and GPU sharing. Select Next and Previous to move between them.
-
Open the Model drop-down menu and select the model to deploy. The menu lists only models of the appliance's current mode. For the two modes, refer to One Mode per Appliance.
-
(Optional) Open the GPU width drop-down menu and select the number of GPUs that one replica of the model runs across. Leave it on The recipe's default to use the width that the model's recipe sets.
-
In Nodes, select every node that should run the model. You cannot select a node whose GPUs are all in use, or that has fewer free GPUs than the GPU width. If the model joins a GPU sharing group that already holds the GPUs on a node, you can select that node. For the full list of reasons a node cannot run a model, refer to Why a Node Cannot Be Chosen.
-
Select Next. The Serving step opens.
-
(Optional) Change the engine's serving settings, such as Extra arguments and Environment variables.
-
Select Next. The GPU sharing step opens.
-
To give the model whole GPUs of its own, turn off the GPU sharing toggle. To share a GPU with the models of a group instead, follow Share a GPU Between Models.
-
Select Deploy.
The appliance brings the model through gate, provision, smoke-test, and ready stages on each chosen node. For that lifecycle, refer to Model Provisioning Lifecycle.
The Models tab lists the semantic router as Semantic Router, beside the models you deploy.
If the model belongs to the other mode, the appliance refuses the deploy with a message such as the following.
<model> runs as text-router-vision, and this box already runs text-router. One box runs one mode, because the semantic router shares one set of GPUs: remove the text-router models first, or move this model into the text-router group.
In the message, <model> is the model you selected. On an appliance that already runs vision-mode models, the message
swaps the two mode names. Remove the models of the current mode first, or deploy a model whose catalog entry belongs to
the current mode.
If the model's catalog entry names no GPU count and no group, the GPU sharing step opens on the group the appliance already runs. For why, refer to One Mode per Appliance.
A deploy from the console always records the nodes you selected. The model runs only on that list. It does not start automatically on a node you add to the cluster later. To run it on additional nodes, refer to Add a Model to More Nodes.
Verify the Model Is Serving
Confirm the model is serving before you route traffic to it.
-
Locate the model in the Model table on the Cluster page.
-
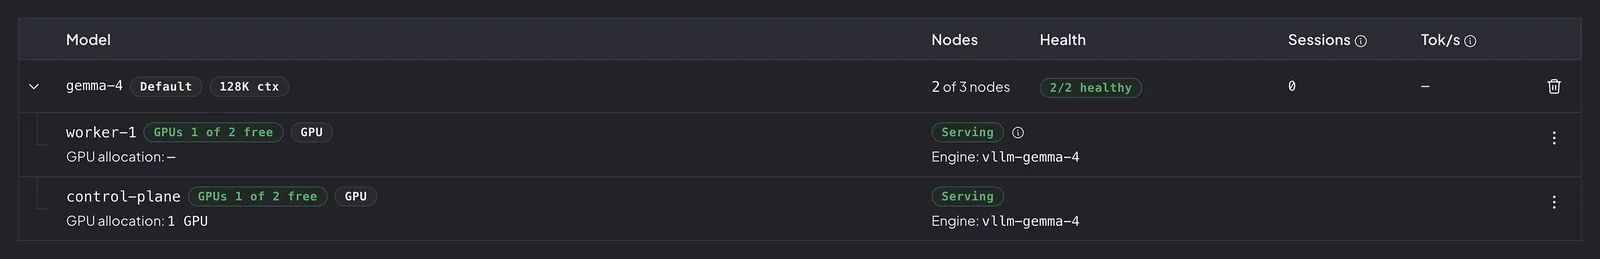
Confirm that the Nodes column reads
N of M nodes, whereNis the number of nodes you chose andMis the number of nodes in the cluster. The health chip counts serving against the chosen set, so2/2 healthymeans every chosen node is serving. -
Expand the model row. Only the nodes you chose are listed. A node you did not select is absent, which means it was never asked to run this model.
-
Confirm that each listed node's state reaches
readyorserving. A state ofdeployingorsmoke-testingmeans the model is still coming online on that node. A state ofWaiting to startmeans the node is chosen and no engine has reported yet. A state offailedorverification failedmeans the model did not come online on that node.
While a model is deploying, a node hosting it can briefly report a Degraded or Not serving state. This is expected
during deployment and clears once the model finishes coming online, at which point the node returns to a healthy state.
For why a model becomes routable only after it passes its smoke test, refer to Model Provisioning Lifecycle.
Review or Change an Engine Argument That Uses JSON
When a { } JSON chip appears on an Extra arguments row in the Deploy a model wizard, use the JSON argument
editor to review or change the value for this deploy. For background on when the recipe carries a JSON-valued argument,
refer to Engine Arguments.
-
On the Cluster page, select the Models tab, and then select Deploy Model. The Deploy a model wizard opens.
-
Choose the model in the Model drop-down menu and its nodes in Nodes, and then select Next to open the Serving step.
-
Under Extra arguments, locate a row whose value is a
{ } JSONchip followed by a one-line preview of its top-level fields. -
Select Edit JSON on that row. The dialog opens with the argument's flag in its title, for example
Edit --kv-transfer-config, and the sub-lineChanges apply to this deploy only. Field names come from the engine. -
On the Form tab, change values in place. Every field carries its type as a badge:
string,number,boolean, ornull. A boolean field renders as atrue/falsebutton pair. A number field rejects non-numeric text withEnter a number.A byte field shows its size in readable units, such as64 GiB.A per-rank byte field also shows the node total for the model's tensor-parallel width. Anullfield is not editable on this tab and readsSet a value on the Raw JSON tab.To add or remove a field, switch to the Raw JSON tab. A note at the top of the Form tab makes this explicit:
Add or remove fields on the Raw JSON tab. The form edits values only, so a typo cannot invent a key the engine ignores. -
On the Raw JSON tab, review the whole document, or add and remove fields. The tab validates on every keystroke. When the text does not parse, the error appears as
Line N: [message], Apply is unavailable, and the Form tab is unavailable with the tooltipFix the JSON error first.Correct the parse error to re-enable both. -
If the editor shows the warning
[key] is the text '[value]', not the boolean [value]. Engines read any non-empty text as true., select Convert to boolean [value]. If it shows the softer nudge for a quoted number, select Convert to number [value]. -
Select Apply to keep the change, or Cancel to discard it. Apply writes the argument back for this deploy only.
Add a Model to More Nodes
To run an already deployed model on additional nodes, change the model's nodes from its row on the Models tab.
-
From the left main menu, select Cluster, and then select the Models tab.
-
On the model's row, open the three-dot menu and select Serving configuration. The nodes and the GPU width open on the placement that the model already has.
-
In Nodes, select each additional node. Save becomes available after you change a value.
-
Select Save. A confirmation states that the model redeploys and stops serving until its engine comes back. Select Save again to confirm.
Remove a Model from a Node
To stop a model on one node and leave it running elsewhere, expand the model row and remove it from that node.
-
From the left main menu, select Cluster, and then select the Models tab.
-
Expand the model row, open the node's three-dot menu, and select Remove.
-
Review the preview, and then select Confirm & apply.
The node stays visible while its engine shuts down. It reads Removing with the message
No longer chosen. Its engine is shutting down. The row disappears once the engine is gone. The model's endpoint and
the remaining chosen nodes keep serving.
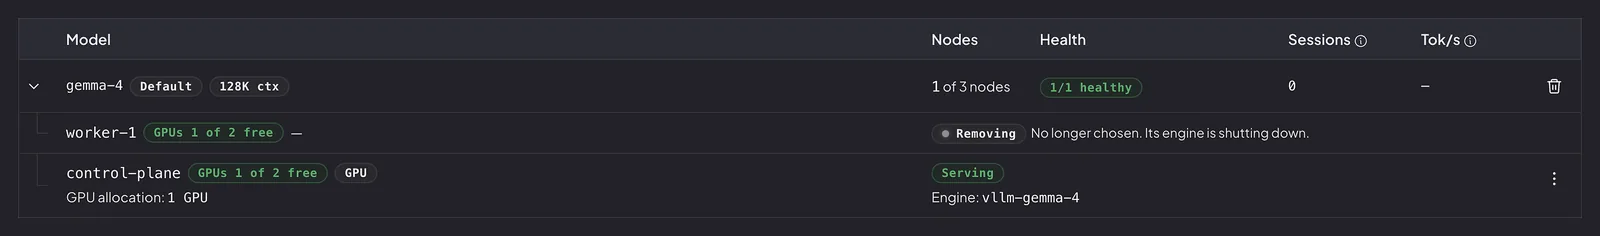
To remove the model from every node, use the trash icon on the model's row instead of a per-node Remove.
Resolve a Blocked Deployment
If a deployment cannot proceed, the wizard explains why. Common reasons include the following:
- You have not chosen a node.
- Every model in the catalog already runs on the cluster, so the Model drop-down menu offers no model. To change a running model, use its row on the Models tab.
- All the GPUs on a node are in use, or the node has fewer free GPUs than the model's GPU width.
- A node's GPU product does not match the GPU product that the model requires.
- The model's weights are not staged on that node, or only the metadata is staged.
- The node's GPU allocation is unknown. Unknown capacity is treated as unusable, not as free.
- The node is not ready, or it is cordoned.
- The GPU sharing plan is refused. For the three refused plans and how to fix each one, refer to Resolve a Refused Sharing Plan.
To resolve the reason, free GPUs on a node by removing another model from that node, stage the model's weights on the node, add capacity to the cluster, or resolve the unknown allocation on the affected nodes. Then deploy the model again. To replace what a node is serving, refer to Replace a Model. For the full list of eligibility reasons, refer to Model Placement.
Next Steps
To deploy a model that shares a GPU with other models, refer to Share a GPU Between Models. To put a newer version or a different model on a node, refer to Replace a Model. For why you would pin a model to some nodes and not others, refer to Model Placement. To let a text-only model answer questions about images, refer to Enable Vision Preprocessing. To bring a model that is not in the certified catalog, refer to Bring Your Own Model.